 Nadia Mohamed
Technical SEO
X-Robots-Tag: The HTTP Header for Noindex on PDFs, Images and Anything Without a <head>
The X-Robots-Tag is an HTTP response header that carries the same indexing rules as the robots meta tag (noindex, nofollow, nosnippet and the rest), but in the response headers instead of the HTML. The typical form is X-Robots-Tag: noindex. Use it to apply those rules to files that have no <head> for a meta tag: PDFs, images, video, JSON and feeds. From February 2027, Microsoft will also read it for AI training and AI grounding choices in Bing and Copilot.
This guide is for the developer who has to ship it. It covers when the header is the right tool and which rules Google supports today. It also covers what happens when the header and the meta tag disagree, and working configuration for Apache, Nginx, IIS, PHP, Netlify, Vercel, Next.js, Cloudflare Workers and Express. Then it shows how to confirm the header with curl and what the header now controls in AI search.
Key takeaways
- The header and the meta tag are equivalent. Google’s specification says “any rule that can be used in a robots
metatag can also be specified as anX-Robots-Tag.” Use the header when there is no HTML, or when one server rule is easier than editing many templates. - When they disagree, the stricter rule wins. Google’s spec says “in the case of conflicting robots rules, the more restrictive rule applies.” A forgotten
noindexheader beats anindexmeta tag. - A URL blocked in
robots.txtnever shows Google its header. If the file is disallowed, thenoindexis never read, so keep anything you want de-indexed crawlable. noarchiveno longer does anything in Google Search, and its role in Bing is ending. Google ignores it. Microsoft is replacingnoarchiveandnocachefor AI uses with newai-trainingandai-groundingvalues, which it will honour from 1 February 2027.- The header is easy to lose. Nginx drops server-level
add_headerlines in any location that sets its own, and a laterres.set()in Express overwrites an earlier one. Both are shown below with real output. - Check with
curl, not a browser extension. Request the exact URL, follow redirects, and read theX-Robots-Taglines that come back.
What the X-Robots-Tag header is
A robots meta tag lives in the HTML: <meta name="robots" content="noindex">. The X-Robots-Tag moves the same instruction into the HTTP response, where it applies to whatever the response contains:
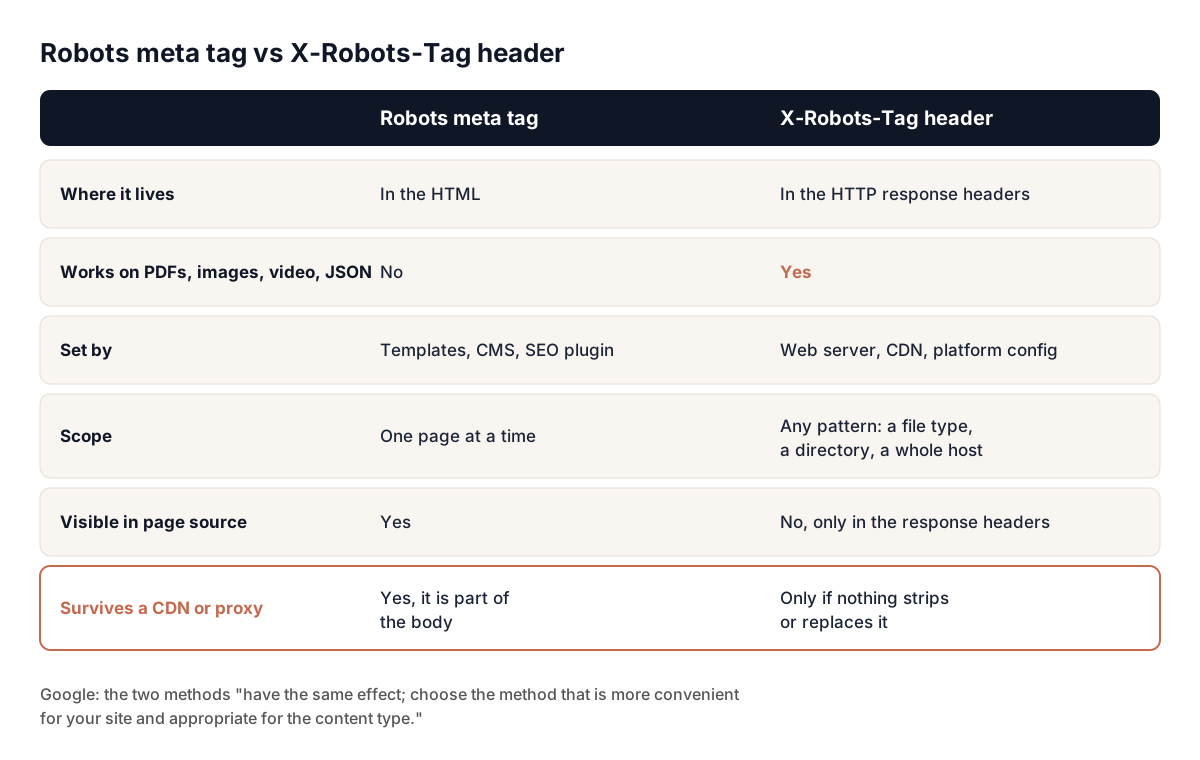
The header and the meta tag compared side by side.
HTTP/1.1 200 OK
Content-Type: application/pdf
X-Robots-Tag: noindex
Google treats the two methods as interchangeable. Its guide to blocking indexing says they “have the same effect; choose the method that is more convenient for your site and appropriate for the content type.” What differs is where you set them and what they can reach.
| Robots meta tag | X-Robots-Tag header | |
|---|---|---|
| Where it lives | In the HTML <head> | In the HTTP response headers |
| Works on PDFs, images, video, JSON | No | Yes |
| Set by | Templates, CMS, SEO plugin | Web server, CDN, platform config or app code |
| Scope | One page at a time | Any pattern: a file type, a directory, a whole host |
| Visible in page source | Yes | No, only in the response headers |
| Survives a CDN or proxy | Yes, it is part of the body | Only if nothing strips or replaces it |
That last row matters. A header can be added, replaced or dropped by every layer between your application and the crawler, which is why this guide spends as much time on verifying as on setting it.
The header is not part of a formal web standard. MDN’s reference lists it under specifications as not part of any current specification. In practice the search engines’ own documentation defines what each value does, which is why this guide quotes Google and Microsoft directly.
If you are still deciding whether a URL should be de-indexed at all or consolidated into another URL, that is a separate question, covered in canonical vs noindex. This page assumes the decision is made and you need to implement it.
When the meta tag cannot do the job
Reach for the header in these situations:
- PDFs, Word documents and spreadsheets. A PDF has no
<head>. Google’s spec says directly that “to block indexing of non-HTML resources, such as PDF files, video files, or image files, use theX-Robots-Tagresponse header instead.” - Images and video. Old product shots, internal diagrams or licensed images you do not want in image search.
noindexon the image response removes that file, andnoimageindexon an HTML page stops the images on it being indexed. - JSON, XML feeds and API responses. Public API endpoints and data files get discovered through links and sitemaps. A
noindexheader keeps them out of results without touching the payload. - Staging and preview environments. One rule at the host level covers every response, including the assets and files a template-level meta tag would miss.
- Whole directories.
/downloads/,/internal/,/print/or an old campaign path, handled in one server rule instead of in every file. - Pages you cannot template. A third-party app mounted on a path, or a legacy system where editing the
<head>means a release you cannot get.
For ordinary HTML pages you control, either method works. The tag itself, including what its snippet rules now do to AI Overviews, is covered in the meta robots tag guide.
The rules Google supports
The list below is taken from Google’s robots meta tag, data-nosnippet and X-Robots-Tag specification, re-checked on 18 November 2026 (the page shows a last update of 24 March 2026). Google also publishes the list in a machine-readable format.
| Rule | What it does in Google Search |
|---|---|
all | No restrictions. The default, so listing it has no effect. |
noindex | Do not show this page, media or resource in search results. |
nofollow | Do not follow the links on this page. |
none | Equivalent to noindex, nofollow. |
nosnippet | No text snippet or video preview. Google says this applies to web search, Google Images, Discover, AI Overviews and AI Mode, and also stops the content being used as a direct input for AI Overviews and AI Mode. |
indexifembedded | Allows the content to be indexed when embedded in another page through an iframe, despite noindex. Only has an effect alongside noindex. |
max-snippet: [number] | Caps the text snippet at that many characters. 0 means no snippet, -1 lets Google choose. |
max-image-preview: [setting] | none, standard or large. large is the setting Google Discover eligibility depends on. |
max-video-preview: [number] | Caps a video preview at that many seconds. 0 allows a static image at most, -1 means no limit. |
notranslate | Do not offer a translation of this result. |
noimageindex | Do not index the images on this page. |
unavailable_after: [date/time] | Do not show this page after the given date. Google accepts widely used formats such as RFC 822, RFC 850 and ISO 8601. |
The spec also states that “the HTTP header, the user agent name, and the specified values are not case sensitive”, so x-robots-tag: NoIndex is read the same way as X-Robots-Tag: noindex.
Rules that no longer do anything in Google
Google keeps a short list of historical rules it now ignores. noarchive “is no longer used by Google Search to control whether a cached link is shown in search results, as the cached link feature no longer exists.” nocache “isn’t used by Google Search”, and nositelinkssearchbox went with the sitelinks search box.
Leaving noarchive in place does no harm in Google. Bing still reads it today, but for AI uses that is changing on a fixed timetable, covered in X-Robots-Tag and AI search below.
Combining rules and targeting one crawler
You can put several rules in one comma-separated header or send the header more than once. Google’s own example combines two headers:
X-Robots-Tag: noimageindex
X-Robots-Tag: unavailable_after: 25 Jun 2010 15:00:00 PST
To target one crawler, put its user agent token before the rules. Rules without a token apply to every crawler:
X-Robots-Tag: googlebot: nofollow
X-Robots-Tag: otherbot: noindex, nofollow
The spec notes that noindex “applies to search engine crawlers”; non-search crawlers such as AdsBot-Google may need rules addressed to them by name. AI training crawlers are controlled mostly through robots.txt tokens, listed in robots.txt for developers.
Header vs meta tag: which wins when they disagree
Neither method outranks the other. Google resolves conflicts by strictness, not by where the rule lives: “In the case of conflicting robots rules, the more restrictive rule applies.” MDN says the same about conflicts “between the X-Robots-Tag HTTP header and the <meta name="robots"> element”.
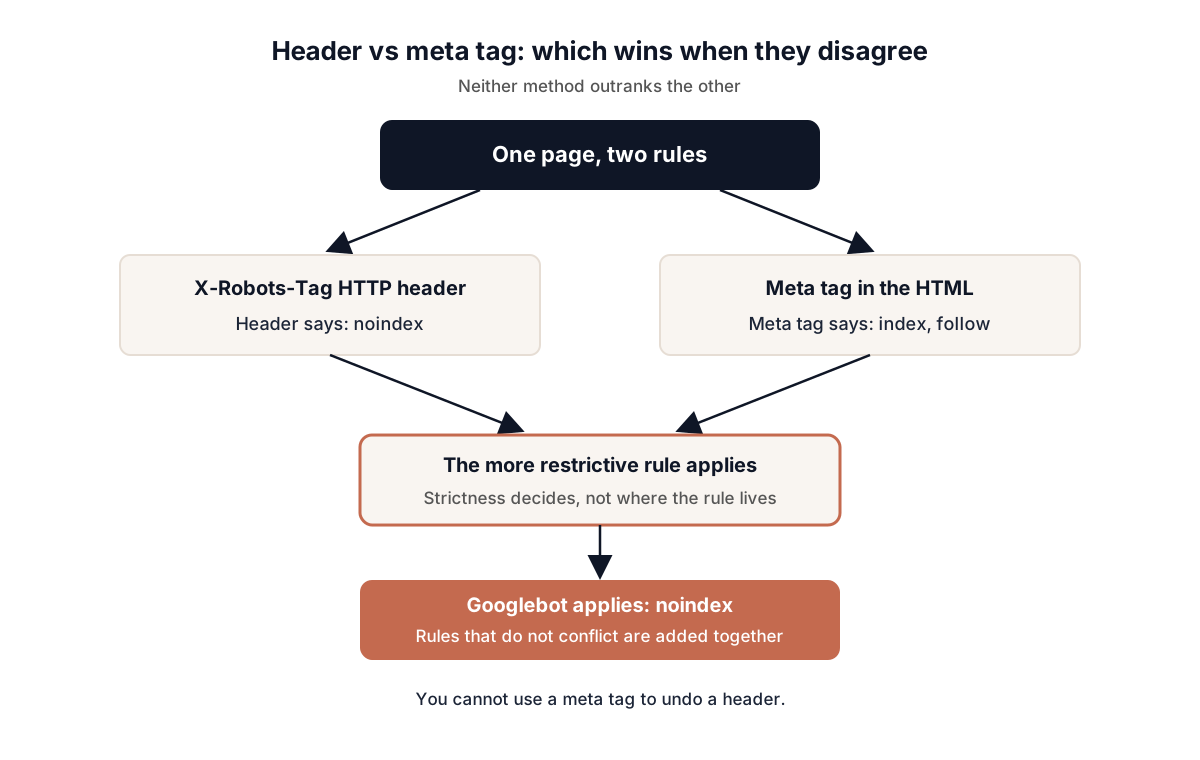
When the two disagree, the more restrictive rule applies.
In practice:
| Header | Meta tag | Google applies |
|---|---|---|
noindex | index | noindex |
| (no header) | noindex | noindex |
nofollow | noindex | noindex, nofollow |
The same goes for preview limits. A header with max-image-preview:large and a meta tag with max-image-preview:standard give you standard.
Rules that do not conflict are added together. Google’s example is a page with nofollow for all robots and noindex for googlebot, which Googlebot reads as noindex, nofollow. The spec’s wording is that “the search engine will use the sum of the negative rules.”
The consequence: you cannot use a meta tag to undo a header. If a CDN rule or a forgotten staging config sends noindex, an index in the template changes nothing. To make a page indexable, remove every restrictive rule at every layer, and pick one place per URL type to own the rules so the next audit does not have to reconcile two.
Server and platform configuration
Every example below sets noindex on a file type or directory. Swap in whichever rules you need. Where a pattern has a trap, the trap follows the code.
Apache: Header set X-Robots-Tag “noindex, nofollow”
Google’s documentation gives this for all PDFs, in .htaccess or httpd.conf, with mod_headers enabled:
<Files ~ "\.pdf$">
  Header set X-Robots-Tag "noindex, nofollow"
</Files>
Read the middle line from left to right:
Headeris themod_headersdirective for changing response headers, so the module has to be enabled.setreplaces any existingX-Robots-Tagon the response with this one.X-Robots-Tagis the header name."noindex, nofollow"is the value. The quotes are required because the value contains a space.noindexkeeps the PDF out of results;nofollowtells Google not to follow links inside it.
The <Files ~ "\.pdf$"> wrapper limits the rule to filenames ending in .pdf. For images:
<Files ~ "\.(png|jpe?g|gif)$">
  Header set X-Robots-Tag "noindex"
</Files>
Use set, not add. The mod_headers documentation warns that add can produce “two (or more) headers having the same name”, while set replaces any previous header with that name.
The same page explains Apache’s two internal header tables, onsuccess (the default) and always. Headers from a CGI or mod_proxy_fcgi backend (a typical PHP setup) live in the always table, so a plain Header set can leave a duplicated header. Apache’s documented pattern for that case is:
Header onsuccess unset X-Robots-Tag
Header always set X-Robots-Tag "noindex"
Nginx
Google’s equivalent for Nginx:
location ~* \.pdf$ {
  add_header X-Robots-Tag "noindex, nofollow";
}
The trap is inheritance. The Nginx headers module documentation says add_header directives “are inherited from the previous configuration level if and only if there are no add_header directives defined on the current level.” Add any header to a location block, and every add_header from the server block stops applying there.
I tested this on Nginx 1.24.0 with a staging-style config: X-Robots-Tag at server level, and an /img/ location that someone later gave a Cache-Control header.
server {
  listen 8081;
  add_header X-Robots-Tag "noindex, nofollow";

  location /img/ {
    add_header Cache-Control "public, max-age=86400";
  }
}
The output:
$ curl -sI localhost:8081/
HTTP/1.1 200 OK
Content-Type: text/html
X-Robots-Tag: noindex, nofollow

$ curl -sI localhost:8081/img/diagram.png
HTTP/1.1 200 OK
Content-Type: image/png
Cache-Control: public, max-age=86400
The image has lost its noindex, and nothing in the config looks wrong. The fix is to repeat the header in every location that has its own add_header. After that change the same request returned both Cache-Control and X-Robots-Tag: noindex, nofollow. On Nginx 1.29.3 and later, the docs describe an add_header_inherit merge; directive that “enables appending values from the previous level to the values defined at the current level.”
Two more details from the same page. add_header only applies to responses with status 200, 201, 204, 206, 301, 302, 303, 304, 307 or 308 unless you add the always parameter. And with no add_header in a location at all, the server-level header is inherited as you would expect.
IIS (web.config)
On Windows servers, IIS sets response headers through the <customHeaders> element. Microsoft’s customHeaders reference says custom response headers “are returned in every response”, so scope the rule by placing it in a <location> for the path you want:
<configuration>
  <location path="downloads">
    <system.webServer>
      <httpProtocol>
        <customHeaders>
          <add name="X-Robots-Tag" value="noindex" />
        </customHeaders>
      </httpProtocol>
    </system.webServer>
  </location>
</configuration>
Without the <location> wrapper, the header applies to the whole site, which is what you want on a staging host and the last thing you want on production. The same element can be set in IIS Manager under HTTP Response Headers, but a web.config in the repository is easier to review and to keep out of production.
PHP and WordPress
When PHP serves the file, for example a download script that streams PDFs, set the header in code:
<?php
header('X-Robots-Tag: noindex, nofollow', true);
header('Content-Type: application/pdf');
readfile($path);
Two rules from the PHP manual decide whether this works. header() “must be called before any actual output is sent, either by normal HTML tags, blank lines in a file, or from PHP.” A stray blank line before <?php is enough to lose it. And by default a call replaces a previous header of the same name; pass false as the second argument to send a second X-Robots-Tag line instead of overwriting the first.
On WordPress, files in wp-content/uploads are normally served by Apache or Nginx directly, not by PHP, so the server rules above are the right place for PDFs and images. Use PHP only for responses WordPress itself generates.
Netlify
Netlify reads headers from a _headers file in the publish directory or from [[headers]] tables in netlify.toml, according to its custom headers documentation. For a downloads directory, in _headers:
/downloads/*
  X-Robots-Tag: noindex
Or the same rule in netlify.toml:
[[headers]]
  for = "/downloads/*"
  [headers.values]
    X-Robots-Tag = "noindex"
Two limitations from the same page matter here. Custom headers “apply only to files Netlify serves from our own backing store”, so they are not applied to proxied content or to URLs handled by a function or edge function, such as server-rendered pages. Those responses have to set the header themselves. And headers declared this way are “global for all builds and cannot be scoped for specific branches or deploy contexts.”
For staging, Netlify documents a workaround: keep per-context header files in a separate folder and copy the right one into the publish directory in that context’s build command.
[context.staging]
  command = "npm run build && cp ./custom-headers/_stagingHeaders ./dist/_headers"
Here _stagingHeaders would contain /* with X-Robots-Tag: noindex.
Vercel
In vercel.json, headers are a list of source patterns with key and value pairs, per the vercel.json reference:
{
  "headers": [
    {
      "source": "/downloads/(.*)",
      "headers": [
        { "key": "X-Robots-Tag", "value": "noindex" }
      ]
    }
  ]
}
Vercel already sends X-Robots-Tag: noindex on some deployments. Its response headers reference says the header is present on preview deployments and on production deployments requested through their unique deployment URL, which includes outdated ones. The same page gives the exception: “Vercel doesn’t add the header when you serve a preview from a custom domain assigned to a Git branch,” such as staging.example.com. That domain is indexable unless you add the header yourself. Vercel’s documented fix scopes the rule to the branch domain with a has condition of type host:
{
  "headers": [
    {
      "source": "/(.*)",
      "has": [{ "type": "host", "value": "staging.example.com" }],
      "headers": [{ "key": "X-Robots-Tag", "value": "noindex" }]
    }
  ]
}
Next.js
next.config.js takes a headers() function that returns source patterns, documented in the Next.js headers reference. The docs note that headers “are checked before the filesystem which includes pages and /public files”, so the rule covers static files in /public too.
// next.config.js
module.exports = {
  async headers() {
    const rules = [
      {
        source: '/downloads/:path*',
        headers: [{ key: 'X-Robots-Tag', value: 'noindex' }],
      },
    ];

    // Vercel sets VERCEL_ENV to "preview" on preview builds.
    if (process.env.VERCEL_ENV === 'preview') {
      rules.push({
        source: '/:path*',
        headers: [{ key: 'X-Robots-Tag', value: 'noindex' }],
      });
    }

    return rules;
  },
};
The preview check follows the VERCEL_ENV pattern in Vercel’s response headers reference. Watch the ordering rule: Next.js says that if two entries match the same path and set the same key, “the last header key will override the first.” Put broad rules first and specific ones last, or the broad one will win. For page-level metadata, the wider framework picture is in the Next.js SEO guide.
Cloudflare Workers
A Worker can add the header to whatever the origin returns. Responses from fetch() are immutable, so Cloudflare’s alter headers example clones the response before changing it:
export default {
  async fetch(request) {
    const response = await fetch(request);
    const url = new URL(request.url);

    // Clone the response so its headers can be changed
    const newResponse = new Response(response.body, response);

    if (url.pathname.endsWith('.pdf') || url.pathname.startsWith('/downloads/')) {
      newResponse.headers.set('X-Robots-Tag', 'noindex');
    }

    return newResponse;
  },
};
This is useful when you cannot change the origin, such as a hosted CMS or a storage bucket. It also works the other way. newResponse.headers.delete('X-Robots-Tag') will strip a header the origin sends, which is exactly what you do not want a forgotten Worker doing to production.
Express
In Express, set the header in middleware for broad rules and in express.static’s setHeaders option for files. This is the server I ran with Express 5.2.1 on Node 22:
import express from 'express';

const app = express();
const isStaging = process.env.APP_ENV === 'staging';

// Staging: noindex every response
if (isStaging) {
  app.use((req, res, next) => {
    res.set('X-Robots-Tag', 'noindex, nofollow');
    next();
  });
}

// Production: noindex PDFs and images served from /public
app.use(express.static('public', {
  setHeaders(res, filePath) {
    if (/\.(pdf|png|jpe?g|gif|webp)$/i.test(filePath)) {
      res.set('X-Robots-Tag', 'noindex');
    }
  },
}));

// A JSON endpoint
app.get('/api/prices', (req, res) => {
  res.set('X-Robots-Tag', 'noindex');
  res.json({ plan: 'pro' });
});

// A Googlebot-only rule plus a rule for every crawler
app.get('/offer', (req, res) => {
  res.append('X-Robots-Tag', 'googlebot: nosnippet');
  res.append('X-Robots-Tag', 'unavailable_after: 2026-12-31');
  res.type('html').send('<p>Ends soon</p>');
});

app.listen(process.env.PORT || 3000);
On the production instance, each rule came back as intended:
$ curl -sI localhost:3001/docs/price-list.pdf
HTTP/1.1 200 OK
X-Robots-Tag: noindex
Content-Type: application/pdf

$ curl -sI localhost:3001/offer
HTTP/1.1 200 OK
X-Robots-Tag: googlebot: nosnippet
X-Robots-Tag: unavailable_after: 2026-12-31
Content-Type: text/html; charset=utf-8
On the staging instance, the PDF did not get the staging rule (output trimmed to the header lines):
$ curl -sI localhost:3002/
X-Robots-Tag: noindex, nofollow

$ curl -sI localhost:3002/docs/price-list.pdf
X-Robots-Tag: noindex
res.set() replaces a header, so the static handler’s noindex overwrote the middleware’s noindex, nofollow. Here it is harmless, because noindex survives. Reverse the two rules (a broad production max-image-preview:large followed by a narrow noindex, or the other way round) and the one you needed is the one that disappears. Switching to res.append() returned both headers, which Google combines:
X-Robots-Tag: noindex, nofollow
X-Robots-Tag: noindex
How to verify the header with curl
Page source will not show the header. Ask the server directly:
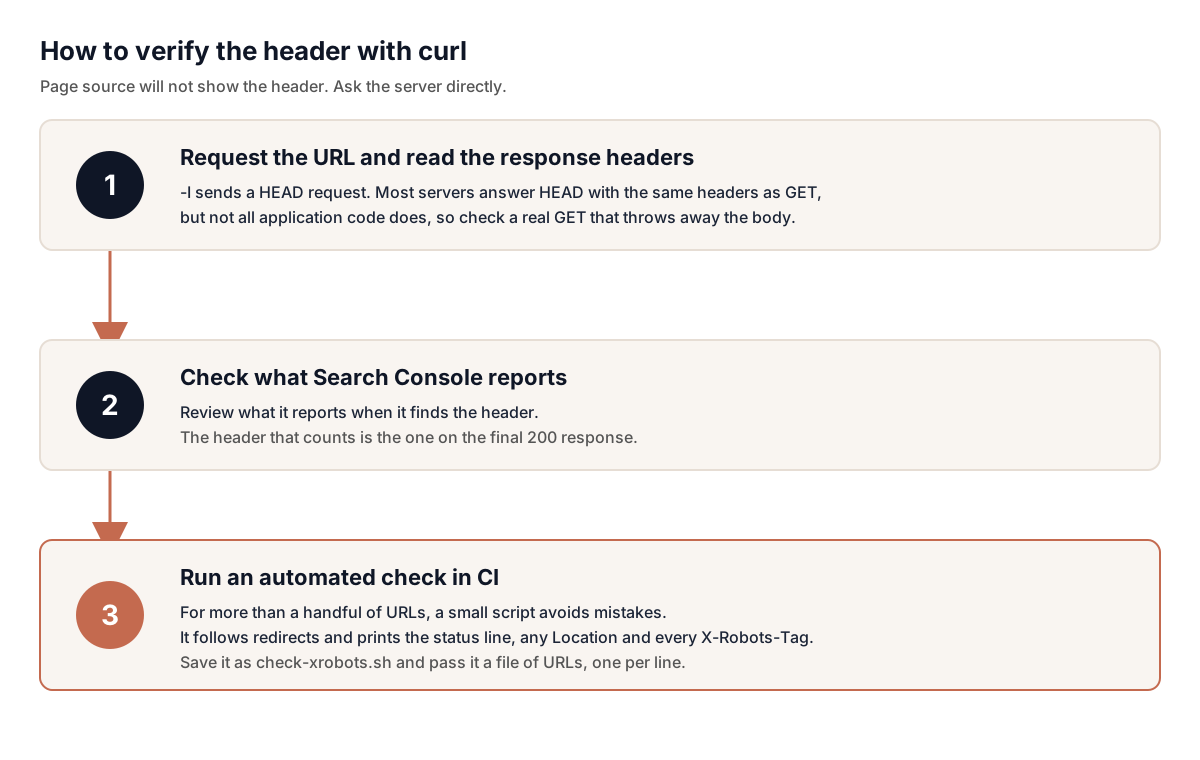
Three ways to prove the header is actually being served.
curl -sI https://example.com/downloads/price-list.pdf | grep -i x-robots-tag-I sends a HEAD request. Most servers answer HEAD with the same headers as GET, but not all application code does, so for anything served by your app, check a real GET that throws away the body:
curl -s -o /dev/null -D - https://example.com/api/prices | grep -iE '^(HTTP/|x-robots-tag:)'For more than a handful of URLs, a small script avoids mistakes. This one sends a GET with a Googlebot user agent string, follows redirects, and prints the status line, any Location and every X-Robots-Tag for each hop. Save it as check-xrobots.sh and pass it a file of URLs, one per line:
#!/usr/bin/env bash
while read -r url; do
  [ -z "$url" ] && continue
  echo "== $url"
  curl -s -o /dev/null -D - -L \
    -A "Mozilla/5.0 (compatible; Googlebot/2.1; +http://www.google.com/bot.html)" \
    "$url" | grep -iE '^(HTTP/|x-robots-tag:|location:)'
done < "${1:-urls.txt}"
Against the local test servers it printed:
== http://localhost:3001/docs/price-list.pdf
HTTP/1.1 200 OK
X-Robots-Tag: noindex
== http://localhost:3001/
HTTP/1.1 200 OK
== http://localhost:3002/
HTTP/1.1 200 OK
X-Robots-Tag: noindex, nofollow
Following redirects matters because the header that counts is the one on the final 200 response. A noindex on a 301 tells Google nothing about the destination. Sending a Googlebot user agent string shows you what a user-agent-sniffing CDN or firewall rule would serve. It does not prove what Google sees, because a server can also treat requests differently by IP.
Turn the check into a deploy gate
A one-off check catches today’s mistake. The expensive mistakes arrive with the next deploy, so run the same script automatically. A minimal pattern for CI, which fails the build if any URL that must stay indexable sends noindex or none:
#!/usr/bin/env bash
set -euo pipefail
fail=0
while read -r url; do
  [ -z "$url" ] && continue
  if curl -s -o /dev/null -D - -L "$url" | grep -i '^x-robots-tag:' \
     | grep -iqE 'noindex|(^|[ ,])none( *,|\s*$)'; then
    echo "BLOCKED: $url"; fail=1
  fi
done < must-index.txt
exit $fail
Keep two lists: must-index.txt with a sample of money pages and templates, and a second list of files that must carry noindex, checked the opposite way. Generating both from the sitemap and a path pattern, and running them after every production deploy, turns an audit finding into a check that runs on its own. It is the same principle behind the rest of SEO automation: a machine check between every human decision.
What Search Console shows
The script shows what your server sends. Search Console shows what Googlebot received. Google’s noindex debugging guidance recommends the URL Inspection tool to see what Googlebot received, and the Page Indexing report to monitor pages from which Googlebot extracted a noindex rule.
In the Page Indexing report, a header-level noindex lands under URL marked ‘noindex’: “When Google tried to index the page it encountered a ‘noindex’ directive and therefore did not index it.” The report does not separate header from meta tag, and its help page tells you to search the page source or “response headers” for the word. If the source is clean, the header is the place to look.
Google also warns that “depending on the importance of the page on the internet, it may take months for Googlebot to revisit a page”, so a correct header will not remove anything until the next crawl. Server logs show when that crawl happens; log file analysis covers how to read them.
robots.txt stops Google seeing the header
This is the mistake that makes a correct header useless. Google’s spec is explicit: robots meta tags and X-Robots-Tag headers “are discovered when a URL is crawled. If a page is disallowed from crawling through the robots.txt file, then any information about indexing or serving rules will not be found and will therefore be ignored.”
The common version: a team wants old PDFs out of Google, adds noindex for /downloads/, and also adds Disallow: /downloads/ to be thorough. Googlebot now never requests the files, never sees the header, and any PDF that was already indexed can stay there, because Google has been told not to look.
The order that works:
- Remove any
Disallowrule covering the URLs. - Serve
X-Robots-Tag: noindexon them and confirm it withcurl. - Wait for a recrawl, or request one through URL Inspection for the URLs that matter.
- Only once they have dropped out, add a
Disallowif you also want to save crawl activity on them. The trade-offs of that step are covered in crawl budget.
Bing works the same way. Its robots meta tag documentation says of noindex: “we need to be able to crawl the page to see this tag, so do not block access to the page.” The full crawl-versus-index model, with the precedence rules for robots.txt, is in robots.txt for developers.
X-Robots-Tag and AI search: Google, Bing, Copilot and ChatGPT
The header now does more than control blue links, but each AI search product reads a different set of signals. Here is what each one documents.
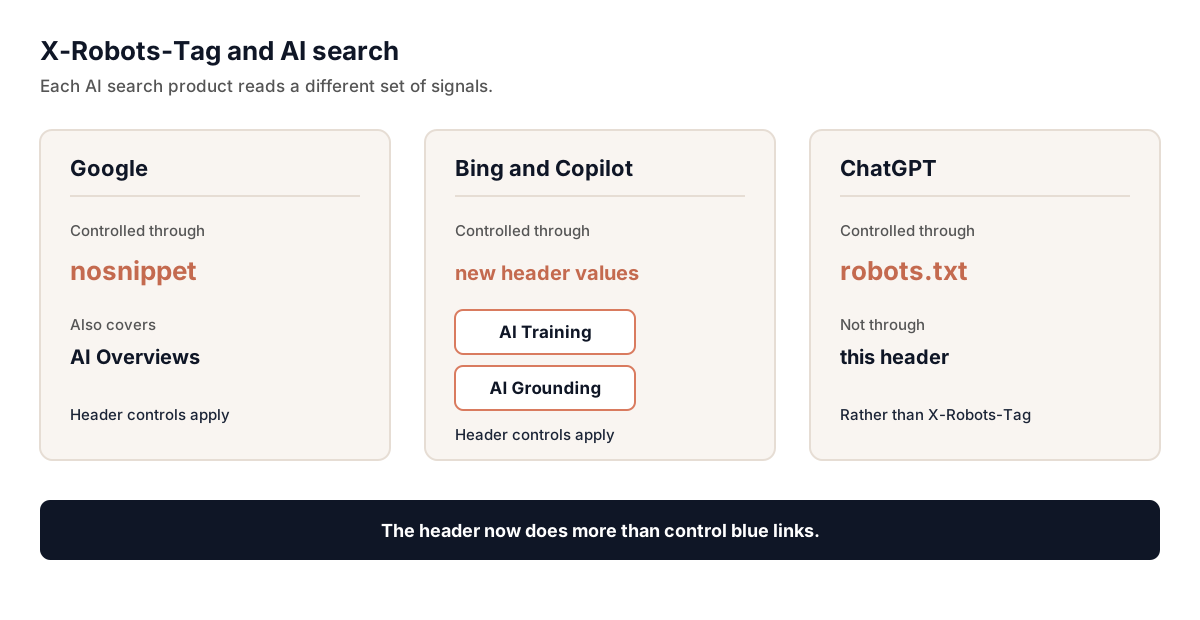
Each AI search product listens to a different control.
Google: AI Overviews and AI Mode
Google has no separate AI value for this header. The existing rules carry over: Google’s spec says nosnippet applies to “AI Overviews, AI Mode” and “will also prevent the content from being used as a direct input for AI Overviews and AI Mode.” max-snippet and data-nosnippet limit what can be quoted. noindex removes the URL from Search, and with it from those features. There is no header value that keeps a page in classic results but out of AI Overviews only. nosnippet is the closest, and it also removes the classic snippet.
Bing and Copilot: noarchive and nocache, then new AI preferences
Bing’s documentation says each of its supported robots meta tags “can also be specified as X-Robots-Tag: in the response header for the page.” Today, two of those values control Copilot:
noarchive: “Do not link in Chat and Copilot,” and do not use the content for training Microsoft’s generative AI foundation models.nocache: “Display only URL/Snippet/Title in Chat or Copilot,” and use only those for training. If a page carries both, Bing treats it asnocache.
That arrangement has an end date. On 30 October 2026 Microsoft announced separate AI Training and AI Grounding preferences that “will replace existing Microsoft preferences NoArchive and NoCache for training and grounding.” Both can be sent in this header:
X-Robots-Tag: Bingbot: ai-training:disallow
X-Robots-Tag: Bingbot: ai-grounding:disallow
ai-grounding also accepts disallowextended. That value limits grounding to Microsoft-operated experiences, which Microsoft lists as AI Mode, AI Overview, Copilot and Microsoft 365, and excludes grounding services it provides to third parties. Training can additionally be set for a site or path in robots.txt with User-Agent: __usage_ai-training. Grounding is page-level only: Microsoft states “there is no site-wide robots.txt grounding preference.” For a whole directory of PDFs, then, the header is the practical way to send it.
The dates that matter, from Microsoft’s announcement:
<StatCallout stats={[ { value: ‘1 Feb 2027’, label: ‘Microsoft starts honouring AI Training and AI Grounding preferences as it crawls’, source: ‘Microsoft Bing’ }, { value: ‘1 Mar 2027’, label: ‘NoArchive and NoCache no longer read as a training or grounding preference’, source: ‘Microsoft Bing’ }, ]} caption=“If you rely on noarchive or nocache to keep content out of Copilot, the header values have to change before March 2027.” />
Three details from the same post. First, sites using noarchive or nocache as of 15 December 2026 can record a temporary grounding preference in Bing Webmaster Tools, which lasts until the page is recrawled or 30 September 2027, whichever comes first. Second, “if we detect new AI Training or AI Grounding preferences on a site, we will disregard any NoArchive and NoCache preferences that may remain on that site.” Third, the preferences “govern use of content, not crawl access”, and Microsoft says they do not change eligibility for Bing search results. Choosing disallow or disallowextended for grounding reduces visibility in AI answers, as the post warns.
What else Copilot looks for before it cites a page is covered in getting cited by Microsoft Copilot. Keep the scope in mind: Bing Webmaster Tools reports on Microsoft surfaces and does not show ChatGPT citations.
ChatGPT: robots.txt, not this header
OpenAI documents its controls in its crawler overview, and they are robots.txt user agents, not X-Robots-Tag values. OAI-SearchBot governs whether a site appears in ChatGPT search answers, and GPTBot governs training. OpenAI says sites opted out of OAI-SearchBot “will not be shown in ChatGPT search answers, though can still appear as navigational links”, and that robots.txt changes can take “~24 hours” to apply to search. The page does not say whether ChatGPT search reads a noindex header, so do not count on one to keep content out of ChatGPT, and do not block OAI-SearchBot if you want to be cited there.
The rule by job: for Google’s AI features, use nosnippet or max-snippet. For Copilot, move to the ai-training and ai-grounding header values now. For ChatGPT, use robots.txt.
Staging and preview environments
Staging is where the header earns its place, because a host-level rule covers HTML, assets, files and API responses at once. It is also the source of the most expensive mistake on this page: the rule that ships to production.
Make the rule depend on the environment rather than on memory:
- Key it to the host or an environment variable, never to a file someone has to remember to delete. The Vercel
has: hostrule, the Next.jsVERCEL_ENVcheck, the Netlify per-context header file, the IIS<location>scope and the ExpressAPP_ENVcheck above all do this. - Put a production check in CI. The deploy gate above fails the pipeline if any must-index URL sends
noindexornone. - Do not rely on
noindexfor privacy. Vercel’s reference makes the point for its own previews: “noindexonly asks search engines not to index a page. Anyone with the URL can still open the deployment.” Anything confidential belongs behind authentication.
If staging has already been indexed, the header alone removes it only as each URL is recrawled. During a site migration, check the new production host for a leftover staging header before launch day, not after.
Common mistakes
These are the failure modes to check in the crawling and indexing phase of a technical SEO audit:
| Mistake | What happens | Fix |
|---|---|---|
Staging noindex left on production | Pages drop out of the index as they are recrawled | Environment-keyed rules plus a CI check on production headers |
Disallow on the same URLs | Google and Bing never read the noindex | Allow crawling until the URLs have dropped out |
| Header and meta tag disagree | The more restrictive rule applies, so an index meta tag cannot undo a noindex header | Pick one source of truth per URL type |
Nginx location with its own add_header | Server-level X-Robots-Tag silently missing on that path | Repeat the header in the location, or use add_header_inherit merge on 1.29.3+ |
Two rules calling set on the same header | The later rule wins and the other is lost | Use append or merge, or combine the values into one header |
PHP output before header() | The header is never sent | Call header() before any output, including blank lines |
| Header set on the redirect, not the destination | The final URL has no rule | Check the 200 response with curl -L |
| Netlify or similar headers on SSR or function routes | Platform header rules are not applied | Set the header in the function’s own response |
| A proxy, Worker or CDN rule rewrites headers | The origin sends the header but the crawler never gets it | Test the public URL, not the origin |
Relying on noarchive in Google | No effect in Google Search | Remove it from your Google checklist |
Relying on noarchive or nocache for Copilot after 1 March 2027 | Microsoft no longer reads them as training or grounding preferences | Send Bingbot: ai-training and ai-grounding values instead |
Frequently asked questions
What is the X-Robots-Tag?
It is an HTTP response header that carries robots rules such as noindex, nofollow and nosnippet. Google says any rule that works in a robots meta tag also works as an X-Robots-Tag. Because it sits in the response headers rather than in the HTML, it works for PDFs, images, video, JSON and other files that cannot hold a meta tag.
Is X-Robots-Tag better than the meta robots tag?
Neither is stronger. Google states the two methods have the same effect. Use the header for non-HTML files, for whole directories or hosts, and for staging environments. Use the meta tag when the rule belongs to a specific page and editors need to be able to see it in the source.
Which wins if the X-Robots-Tag and the meta robots tag disagree?
The more restrictive rule. Google’s specification says “in the case of conflicting robots rules, the more restrictive rule applies,” so a noindex header overrides an index meta tag, and the reverse. Rules that do not conflict are combined.
How do I noindex a PDF?
Serve the PDF with an X-Robots-Tag: noindex header from your web server, CDN or platform config. On Apache that is Header set X-Robots-Tag "noindex, nofollow" inside a <Files ~ "\.pdf$"> block. Confirm it with curl -sI on the file’s URL, and make sure the PDF is not blocked in robots.txt, or Google will never read the header. An indexed PDF drops out only after Google recrawls it.
Can I target Googlebot only with the X-Robots-Tag?
Yes. Put the user agent token before the rules, for example X-Robots-Tag: googlebot: noindex. Rules without a token apply to every crawler. If both are present, Google combines the restrictive rules that apply to it.
Does the X-Robots-Tag control Copilot and ChatGPT?
For Copilot, yes. Bing reads noarchive and nocache in the header today, and from 1 February 2027 Microsoft honours the new Bingbot: ai-training:disallow and Bingbot: ai-grounding:disallow values as it crawls. After 1 March 2027 it no longer reads noarchive or nocache as a training or grounding preference. For ChatGPT, OpenAI documents robots.txt controls for OAI-SearchBot and GPTBot, not header values.
Does Google still support noarchive?
No. Google’s specification lists noarchive among historical rules it ignores, because the cached link feature it controlled no longer exists. It does no harm to leave it in place, and Bing still reads it for now, but it has no effect in Google Search.
Why does Google still show a URL I set to noindex?
Usually because Google has not recrawled it since the header was added, or because robots.txt blocks the URL so the header is never seen. Check the live response with curl, remove any Disallow covering it, and request a recrawl through URL Inspection. If the header is missing on the public URL but present at the origin, something in between is removing it.
If you want the indexing rules on your site checked end to end, from server config through CDN to what Googlebot and Bingbot actually receive, that is part of my technical SEO and GEO work.